Build Reliable Pipelines
Work with SQL, Python, cloud storage, APIs, ETL and ELT, orchestration, and repeatable deployment practices.
Learn how data moves, where failures occur and how to recover safely.
Learn on your own time with practical courses built by experienced AI and data professionals.
This site is protected by Google reCAPTCHA and the Google Privacy Policy and Terms of Service apply.
A practical guide to building reliable, production-minded data platforms — from raw operational data to pipelines, modeling, cloud platforms, AI workflows and production engineering.
The digital edition is delivered by Amazon Kindle. The Soft Cover is posted to you in Bulgaria by Speedy, and delivery is paid separately to Speedy. Maximum 2 Soft Cover books per order.
This book is a practical path from raw operational data to a reliable, production-minded data platform.
Each chapter combines essential concepts with implementation choices, failure modes and exercises you can apply to your own project.
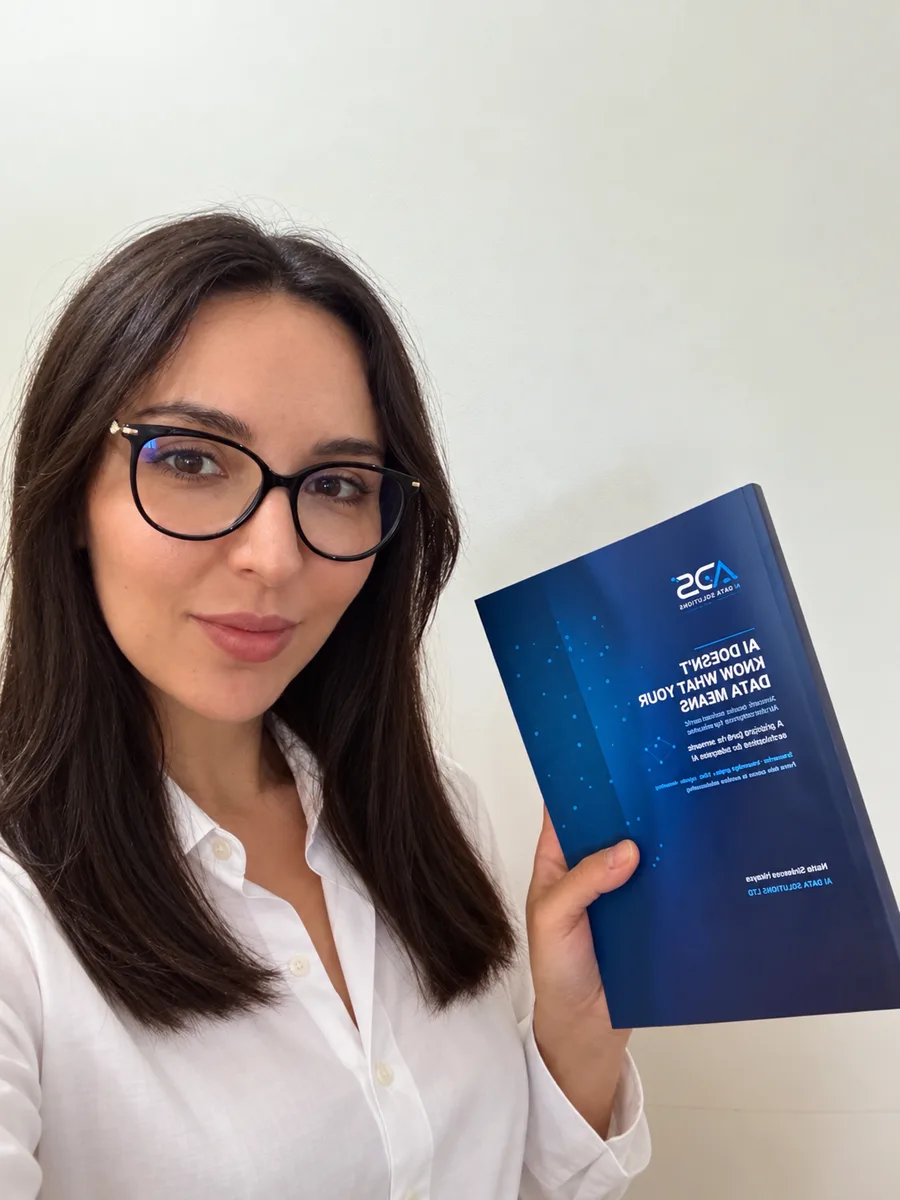
Maria Hristova is a Solution Architect, author, and inventor working at the intersection of enterprise data, semantics, knowledge graphs, and artificial intelligence.
She is the author of "AI Doesn’t Know What Your Data Means", which explores one of the fundamental challenges facing enterprise AI: giving an AI system access to data does not mean it understands what that data represents. Her work focuses on how semantic models, ontologies, identity, provenance, and knowledge graphs can provide the foundation for more grounded, explainable, and trustworthy AI.
Maria is also the inventor of "Ontelyx", an approach designed to transform fragmented enterprise information into connected, machine-understandable knowledge that can support semantic discovery, AI reasoning, and intelligent agents.
Five threads run through the chapters, each building on the one before it.
Work with SQL, Python, cloud storage, APIs, ETL and ELT, orchestration, and repeatable deployment practices.
Learn how data moves, where failures occur and how to recover safely.
Design models, tests, contracts and monitoring that make analytics dependable.
Learn why idempotency, lineage, data quality and clear ownership matter when a pipeline runs every day.
Apply Git and CI/CD, Airflow, dbt, Snowflake, Databricks, Spark and cloud services in the context of real engineering decisions rather than isolated tool demonstrations.
Evaluate RAG and LLM workflows, protect confidential data, control access and turn security checks into part of the delivery process.
Finish with a portfolio-ready platform that brings the pieces together in an end-to-end project with architecture, tests, automation, documentation and evidence of how the system handles failure.
Build the engineering mindset behind reliable modern data platforms.